
Creating a Fabric workspace takes about 30 seconds. Restructuring workspaces after people have built content in them takes a lot longer. Moving content to another workspace usually means redeploying or recreating it, and anything bound to the old item IDs has to be rebound: reports connected to a semantic model, a notebook’s default lakehouse, pipeline activities, and shortcuts. Item-level shares, app content, and links people saved don’t carry over either.
Most of that rework is avoidable if you make a handful of design decisions before anyone starts building. None of these decisions has a single right answer. The right choice depends on your organization’s size, skills, security requirements, and how much self-service you want to support. But I’d much rather see them made deliberately, before the first workspace exists, than left at the defaults and discovered later. For each decision, I’ll cover the options, what should drive the choice, and the platform constraints that narrow it down.
1. Capacity and region
I put region first because it’s one of the hardest decisions to undo. Workspaces with non-movable Fabric items can’t be reassigned to a capacity in another region until those items are removed. You also can’t change the region of an existing capacity; you create a new capacity and move workspaces to it. If you enable tenant-level Private Link, the first Spark job or Lakehouse table operation in a workspace allocates a managed virtual network, and from then on that workspace can’t move to a capacity in another region at all. See decision 2 for more on Private Link.
What should drive the choice
- Where your source data lives, and whether any integration requires region matching
- Data residency requirements
- Your tenant’s home region, and whether you’ll need a capacity outside it
- Any requirements to isolate workloads, costs, or departments
Platform constraints
- Dataverse Link to Fabric requires a workspace on a capacity in the same region as the Dataverse environment.
- A Fabric Copilot capacity is only supported in the tenant’s home region and must be at least F2 or P1. If your data capacities are in a different region than your home region, plan for a separate capacity to bill Copilot usage.
- Not every workload is available in every region, and SQL database in Fabric must be available in both the tenant home region and the capacity region. Check the region availability page against the items you expect to build.
2. Network security posture
Some network controls change what your entire tenant can do, so this is one to settle before anyone builds anything. Inbound protection can be applied at the tenant level or the workspace level, and outbound connectivity to private resources is its own set of choices.
Options
- Tenant-level inbound protection: Private Link and Block Public Internet Access
- Workspace-level inbound protection: workspace Private Link and workspace IP firewall rules
- Identity-based controls instead of network controls: Conditional Access policies requiring MFA, compliant devices, or named locations
- Outbound access to private sources: managed private endpoints (which provision a managed virtual network), gateways, or trusted workspace access
What should drive the choice
- What you’re actually protecting against: unauthorized access, data exfiltration, or a hard requirement that data never crosses the public internet. Only the last one requires Private Link.
- Whether the restriction is needed for the whole tenant or only for specific workspaces
- Which Fabric features your users need
Platform constraints
- The tenant-level controls apply to every workspace, and they disable or degrade a long list of features. Microsoft keeps the full list in Private links for Fabric tenants. These three are the ones most likely to change your plans:
- On-premises data gateways aren’t supported and fail to register. Virtual network data gateways work.
- Only some mirroring sources support Private Link, such as SQL Server 2025 and open mirroring. With Block Public Internet Access enabled, mirrored databases from other sources pause and can’t be started.
- A pipeline can’t copy data into or out of a Fabric Data Warehouse.
- With Private Link enabled, the first Spark job or Lakehouse table operation in a workspace provisions a managed virtual network. That disables starter pools, so Spark sessions take minutes to start, and the workspace can’t move to a capacity in another region while the managed virtual network is allocated.
- Workspace-level protection isn’t a lighter version of the tenant-level controls. It has its own limitations and adds networking infrastructure to build and maintain.
3. Who builds and owns content
Who builds and maintains content affects how many workspaces you need and who administers them, so it’s worth deciding before you design the workspace structure.
Options
- Centralized: a central data or BI team builds everything
- Self-service: departments build and maintain their own content
- Hybrid: a central team owns shared data and models, and departments build on top of them
If you allow self-service, define what it includes. Supporting departments that build reports on centrally managed semantic models is very different from supporting departments that build their own lakehouses and pipelines.
What should drive the choice
- Skill levels outside the central team
- How much support the central team can provide
- Governance maturity: whether you have standards, reviews, and monitoring in place to support self-service at scale
Platform constraints
- Workspace creation is controlled by a tenant setting that can be limited to specific security groups. Deciding who gets that permission is part of this decision.
4. How to split workspaces
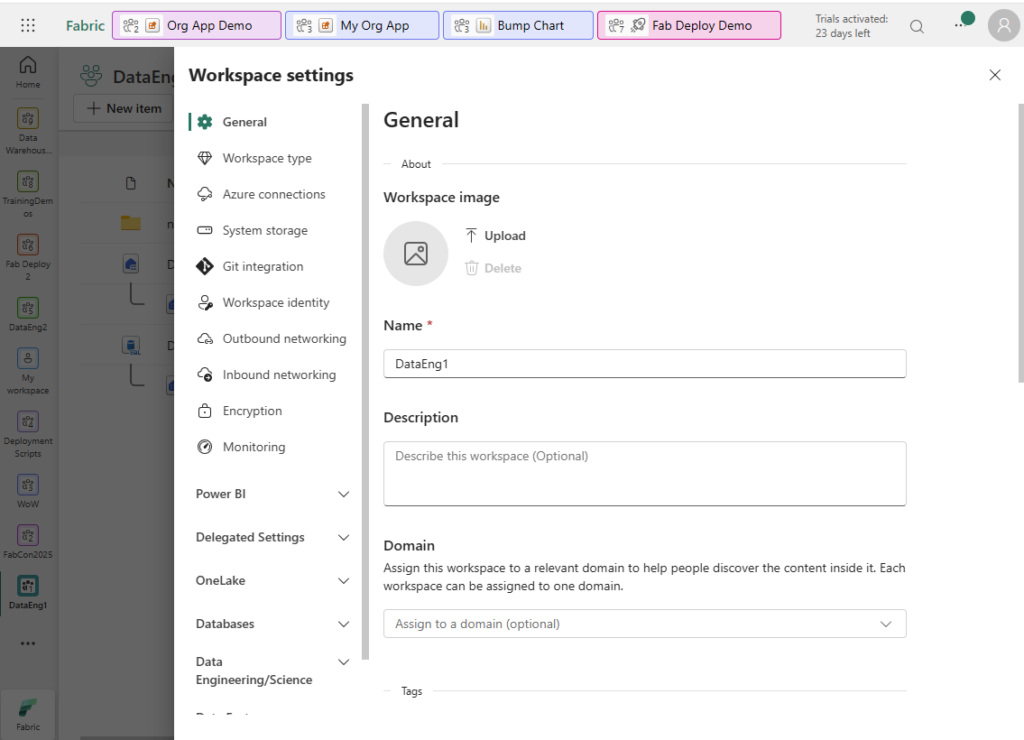
A workspace is the boundary for a lot of settings at once. So when you decide how to divide content into workspaces, you’re really deciding on security, deployment, and cost boundaries.
Options
- By subject area or data product
- By department or business unit
- By layer or function, such as separating data engineering items from reporting items
- A combination, such as department plus layer
Whichever split you choose, environments multiply it. Each dev, test, and prod stage is usually its own workspace, so decide the split and the environment count together. See decision 5 for more on environments.
What should drive the choice
- Who needs access to what. Workspace roles apply to every item in the workspace.
- What gets deployed together. Content that’s released on a different schedule or by a different team usually belongs in a different workspace.
- Which capacity the content should run on, for cost allocation or workload isolation
- How many workspaces your team can realistically administer
Platform constraints
Each of these is set per workspace, not per item:
- Capacity assignment
- Git connection
- Deployment pipeline stage
- Domain assignment
- Workspace identity
- Workspace-level network settings
- Org app (an org app contains content from a single workspace)
5. Environments
In Fabric, an environment is usually a separate workspace, so the number of environments you choose directly affects how many workspaces you create and manage.
Things to decide
- Your standard number of stages, such as two (dev and prod), three (dev, test, and prod), or more
- Whether each prod workspace gets its own dev workspace, or several prod workspaces share one dev workspace
- Which workspaces need the full set of environments. Self-service workspaces might need only one or two, and experiments or proofs of concept can either start with multiple environments or get them once they’re headed to production.
What should drive the choice
- Whether you have people who will actually test in a test stage
- The deployment tool you choose. See decision 6 for deployment options.
- Workspace count. Every environment multiplies the number of workspaces to secure and administer.
Platform constraints
- In a deployment pipeline, each stage is assigned one workspace, and a workspace can only be assigned to one pipeline. A shared dev workspace can’t feed several pipelines.
- Deployment pipelines support 2 to 10 stages.
6. Source control and deployment
I recommend deciding how content moves between environments before developers start building. Retrofitting source control means reconciling existing items with a repo and reworking anything that hard-codes environment-specific values, such as workspace and lakehouse IDs.
Things to decide
- Git provider: Azure DevOps or GitHub
- Deployment tool: Fabric deployment pipelines, Git-based deployment with a tool like fabric-cicd, custom automation that calls the Fabric REST APIs (such as GitHub Actions or notebooks), or a combination
- Branching: a branch per environment, or a single main branch deployed to each environment
- Authentication for the Git connection, including whether it depends on an individual user’s credentials
What should drive the choice
- Which item types you’ll build. Not every item type supports Git integration or deployment pipelines.
- Whether your team already works in pull requests and build pipelines
- How you’ll handle values that differ per environment (connections, lakehouse bindings, parameters)
Platform constraints
- The Azure DevOps source control connection supports two authentication methods: OAuth 2.0 and service principal. Workspace identity isn’t one of them.
- With deployment pipelines, each stage is assigned one workspace, and a workspace can only be assigned to one pipeline. See decision 5 for how that affects your environments.
7. Naming conventions
Naming conventions are easiest to agree on before the first item is created. Once other items, connections, code, and reports reference an item, renaming it is tedious and error-prone.
Things to decide
- Workspace names: whether they include department, subject, environment, or ownership type
- Item names: whether to use type prefixes, which casing, and which separator
- Data store objects: schema and table naming, including how medallion layers show up (if you use them)
- Business-facing names: whether semantic model tables and columns use technical names or friendly names with spaces
- Capacities, connections, and gateways, which admins see more than end users do
What should drive the choice
- Who reads the name. End users browsing the OneLake catalog need different names than engineers writing code.
- Consistency with standards you already use in Azure or SQL Server
- What sorts and filters well in the workspace list and the OneLake catalog
Platform constraints
- Microsoft doesn’t publish an official naming standard for Fabric items like the Cloud Adoption Framework provides for Azure resources. There are community examples, such as those from Data Mozart, XTIVIA, and datamartin.ca, but you’ll need to adapt them.
- Lakehouse names must begin with a letter and can only contain letters, numbers, and underscores. A convention with spaces or hyphens won’t work for every item type.
- Lakehouse schema names can only contain letters, numbers, and underscores.
8. Domains
Domains are where some tenant-level governance settings can be delegated to the business. Discoverability in the OneLake catalog is helpful, but delegation is the bigger reason to think carefully about what your domains represent and who administers them.
Options
- Domains by department or business unit
- Domains by subject area or data product
- A domain for shared, company-wide content alongside department domains
- No domains yet, if you don’t need delegated governance or catalog filtering
What should drive the choice
- Whether different parts of the business need different governance settings
- Who should be a domain admin. Ideally, it’s someone who knows the data and the rules that apply to it.
- Which workspace admins should be allowed to assign their workspaces to a domain (domain contributors)
Platform constraints
- Settings that can be delegated to domain admins include a domain-level default sensitivity label and certification settings: whether certification is enabled, who the certifiers are, and the documentation URL.
- Domain assignment doesn’t affect access. Permissions still come from workspace roles and item permissions.
- A default domain can automatically assign new workspaces created by specified users or groups.
- Tags can be created at the tenant scope or the domain scope. Domain-scoped tags are only available to items in workspaces assigned to that domain or its subdomains.
9. Access and distribution
I think about how builders get access separately from how consumers get content. Mixing the two, such as giving report consumers the Viewer role in a workspace full of engineering items, makes permissions harder to audit.
Options
- Workspace roles (Admin, Member, Contributor, Viewer), assigned to groups rather than individuals
- Direct item sharing
- Workspace apps
- Org apps
What should drive the choice
- Whether consumers should see everything in a workspace or a curated subset
- Licensing: whether consumers have Pro or PPU licenses, or rely on the content being on an F64 or larger capacity
Platform constraints
- Workspace apps and org apps each contain content from a single workspace. If consumers need content from several workspaces in one app, that affects how you split workspaces. See decision 4 for more on splitting workspaces.
- Deploying through a deployment pipeline doesn’t update the workspace app. Updating the app is a separate step in your release process.
10. Classification
Sensitivity labels and tags do different jobs, and you can use both. Decide what each one represents before people start applying them inconsistently.
Things to decide
- Which sensitivity labels apply to Fabric items, and whether a default label should apply by tenant or by domain
- What tags represent: data content, project, cost center, lifecycle status, or something else
- Who creates tags and who is expected to apply them
- Whether tag names follow a pattern that makes them easy to filter
What should drive the choice
- Labels drive protection. If a classification needs to restrict access or trigger data loss prevention, it belongs in a sensitivity label.
- Tags are for organizing and finding content. They don’t enforce anything.
- The questions people will ask when searching the OneLake catalog
Platform constraints
- An item can have only one sensitivity label.
- Fabric admins create tenant-level tags, and Fabric or domain admins create domain-level tags. Tags are applied by users with the Contributor role or higher in the workspace.
- Tags are single values, not key-value pairs. Tag names can include special characters, so you can simulate that structure by naming a tag
Facet: Value.
Before you click New workspace
Here are the questions I’d bring to a planning session:
- Which region should each capacity be in, and do any sources or features require a specific region?
- Which network controls do you actually need, and at which level?
- Who builds and maintains content, and how much self-service will you support?
- How will you split content into workspaces?
- How many environments do you need, and how do they map to workspaces?
- How will content move between environments, and where does it live in source control?
- What naming conventions will you use for workspaces, items, and objects?
- What do domains represent, and which settings will domain admins control?
- How do builders get access, and how do consumers get content?
- What do sensitivity labels and tags each represent?
You can change most of these answers later. It’s just much cheaper to answer them up front.
If you’re already working in Fabric, what do you wish you had decided before you started? Or which decision came back to bite you later? Let me know in the comments.